Featured post

Linux Internals: How /proc/self/mem writes to unwritable memory

Introduction

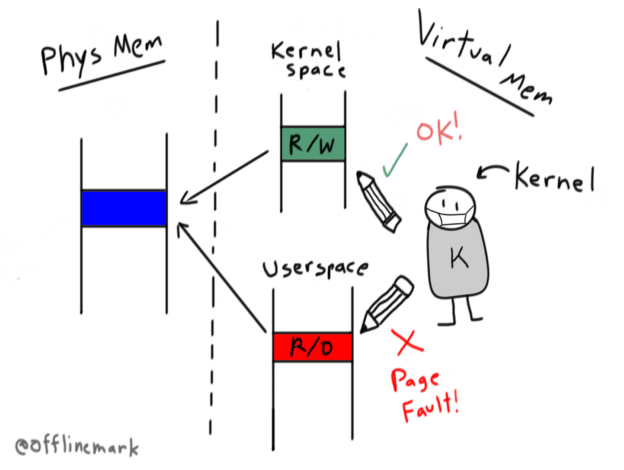
An obscure quirk of the /proc/*/mem pseudofile is its β€œpunch through” semantics. Writes performed through this file will succeed even if the destination virtual memory is marked unwritable. In fact, this behavior is intentional and actively used by projects such as the Julia JIT compiler and rr debugger.

This behavior raises some questions: Is privileged code subject to virtual memory permissions? In general, to what degree can the hardware inhibit kernel memory access?

By exploring these questions1, this article will shed light on the nuanced relationship between an operating system and the hardware it runs on. We’ll examine the constraints the CPU can impose on the kernel, and how the kernel can bypass these constraints.

Continue reading →
Featured post

Double fetches, scheduling algorithms, and onion rings

Most people thought I was crazy for doing this, but I spent the last few months of my gap year working as a short order cook at a family-owned fast-food restaurant. (More on this here.) I’m a programmer by trade, so I enjoyed thinking about the restaurant’s systems from a programmer’s point of view. Here’s some thoughts about two such systems.

Continue reading →
Featured post

What they don’t tell you about demand paging in school

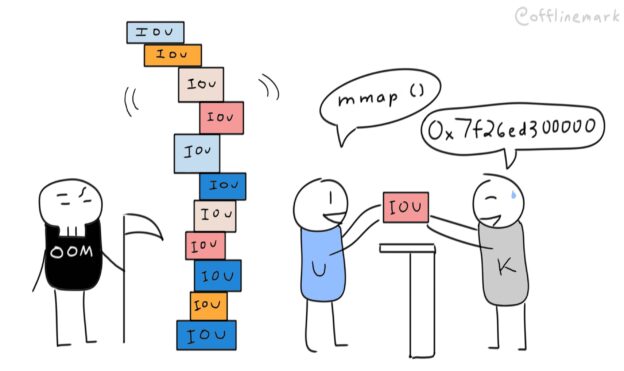
This post details my adventures with the Linux virtual memory subsystem, and my discovery of a creative way to taunt the OOM (out of memory) killer by accumulating memory in the kernel, rather than in userspace.

Keep reading and you’ll learn:

  • Internal details of the Linux kernel’s demand paging implementation
  • How to exploit virtual memory to implement highly efficient sparse data structures
  • What page tables are and how to calculate the memory overhead incurred by them
  • A cute way to get killed by the OOM killer while appearing to consume very little memory (great for parties)

Note: Victor Michel wrote a great follow up to this post here.

Continue reading →
Featured post

How setjmp and longjmp work (2016)

Pretty recently I learned about setjmp() and longjmp(). They’re a neat pair of libc functions which allow you to save your program’s current execution context and resume it at an arbitrary point in the future (with some caveats2). If you’re wondering why this is particularly useful, to quote the manpage, one of their main use cases is β€œβ€¦for dealing with errors and interrupts encountered in a low-level subroutine of a program.” These functions can be used for more sophisticated error handling than simple error code return values.

I was curious how these functions worked, so I decided to take a look at musl libc’s implementation for x86. First, I’ll explain their interfaces and show an example usage program. Next, since this post isn’t aimed at the assembly wizard, I’ll cover some basics of x86 and Linux calling convention to provide some required background knowledge. Lastly, I’ll walk through the source, line by line.

Continue reading →

My OSdev Roadmap

https://www.youtube.com/@offlinemark

Milestone 1: JOS

  • βœ… Lab 1: Boot
  • βœ… Lab 2: Memory Management
  • βœ… Lab 3: User Environments (Processes)
  • βœ… Lab 4: Preemptive Multitasking
  • βœ… Lab 5: Filesystem, Spawn, Shell
  • βœ… Lab 6: Network card driver

Milestone 2: Modern OS Foundation

  • βœ… Try bootloaders
    • βœ… Multiboot V1 (Grub)
    • βœ… Multiboot V2 (Grub)
    • βœ… Limine (BIOS)
    • βœ… Limine (UEFI)
  • βœ… C++ support in JOS
  • βœ… Modern LLVM toolchain
    • βœ… Clang instead of GCC
    • βœ… cc-runtime (compiler-rt) instead of libgcc
    • βœ… LLD Linker
    • βœ… LLDB Debugger
  • βœ… Port JOS to CMake
  • βœ… Third party C++ libraries
    • βœ… STL
    • βœ… ETL
    • βœ… Frigg

Milestone 3:

  • βœ… Basic virtual address space management (mapping)
  • βœ… Basic Interrupts/Exception support
  • βœ… Basic Scheduler (Round Robin)
    • βœ… Deferred task cleanup
  • βœ… Task stack guard pages
  • βœ… Cooperative multitasking
    • βœ… taskYield() – cooperative yield
  • Task Scheduler APIs
    • βœ… taskExit()
    • βœ… taskWaitForTaskExit()
    • βœ… taskSleepCpuCycles()
  • βœ… Preemptive Multitasking
    • βœ… LAPIC Timer Interrupt
  • Concurrency Primitives
    • Spinlock
    • Mutex
    • Semaphore
    • Condition Variable?
  • Drivers
    • Serial console

Future:

  • Processes (Task Groups)
  • More advanced scheduler
  • Audio
  • USB
  • Kernel Objects
  • SMP / Multicore
  • Per CPU State (GS)
  • Coroutines (In Kernel?)
  • Userspace
  • IPC
  • Graphics
  • Drivers
  • Filesystem
  • ASLR
  • Accelerate syscalls (Syscall instruction)
  • ARM64
  • RISCV

How learning compounds

Unlike money, learning doesn’t compound passively. If you learn something, then sit around, you don’t automatically get more learning.

Learning compounds in the sense that the more you learn, the easier it becomes to learn new things. Therefore your rate of learning increases over time, allowing you to learn more.

As you do more things, it allows you to do new things more easily, because you’ll already have done some fundamental building blocks. For example, it was easier for me to start an online clothing brand for fun, since I already have experience with graphic design and websites from past projects.

If I didn’t already have experience with graphic design, or setting up a website, it would have taken me much longer to set up the online clothing brand.

Additionally, the more you learn, the easier it is to create novelty. This is because it is much easier to generate novelty by remixing two things together, than by generating it from scratch. The more you have experience with, the more combinations you can remix.

libc++ is surprisingly hard to use for my kernel

libc++ is surprisingly hard to use for my kernel

I currently use libstdc++, but that’s the only GNU part of my toolchain left. I use LLVM for everything else (clang, compiler-rt, lldb, clangd…)

Here are a few screenshots of the additional porting work to make libc++ work

Libraries for freestanding C++

Libraries for freestanding C++ development:

Not freestanding, but interesting:

What I learned from yoga

Yoga classes often end with “Shavasana”, which is a period of full relaxation, lying on your back.

When I first tried yoga, I disliked this. I didn’t understand it and thought it was a waste of time.

Now, it’s my favorite part. I actively look forward to the Shavasana period, after the sometimes-intense yoga practice.

I apply this is in my normal life too, now. After ending a hard work day or even just a hard work session, I take a moment to Shavasana (if not physically, then mentally). It doesn’t have to take a lot of time.

There’s a certain wisdom in the recognition that after a strenuous period, it’s good to explicitly block some time to decompress, unwind, and relax.

How to sharpen the saw

“Sharpening the saw” is a term from “The 7 Habits of Highly Effective People”.

I’m lucky enough to get time in my day job to do this. Here’s how I use that time, specifically:

  1. Systems maintenance
  2. Learning
  3. Systems improvement
  4. Innovation

Systems Maintenance

This is the first priority during sharpening time. It means attending to natural breakages, accumulations of disorder & chaos.

Over time, systems naturally accumulate chaos. The work of maintenance is simply to bring a system back up to the status quo.

It does not mean going beyond to try to fundamentally improve a system (that comes later). However, sometimes it’s easier to replace a system instead of doing maintenance on it.

Examples:

  • Doing a slower and more thorough GTD review & meditation
  • Cleaning out my hard disk and deleting old files
  • Fixing broken parts of my development environment
  • Routine software & toolchain upgrades

Learning

Learning could mean learning to use my tools better, learning more about the codebase I work in, or more general learning that is still relevant to my daily work.

The idea here is to focus on key leverage points that amplify your ability to do the main workstream better.

If I use tools daily, learning to use them 1% or 5% better can yield impactful differences in what I can accomplish.

If I work in a codebase daily, improving my understanding of certain corners where I have shaky understanding can also be a force multiplier for how effectively I can work, and what kinds of projects I can contribute to.

Examples:

  • Watching videos about Apple Notes/Notion/Miro to learn new features
  • Asking AI to give me exercises to do to learn parts of the codebase better

Systems Improvement

For example, if you were cleaning up your note taking system, maintenance would look like cleaning things up within the existing system, but wouldn’t go as far as deeper thinking about whether you should fundamentally change the system, switch products, etc.

That’s the thinking that comes in the Systems Improvement phase, where you go one level deeper and examine the system holistically and consider larger scale changes, repairs, or improvements.

Maybe the system doesn’t even exist, which is an outstanding liability.

Examples:

  • Should I completely switch from Apple Notes to Notion?
  • I have no data backup strategy. What would a basic one look like?

Innovation

Innovation is taking time to explore new, experimental, or unconventional ideas that would never get prioritized into the main workstream. Nevertheless, these experiments can be significant points of leverage. (GMail came from Google’s “20% time”).

Devtools update 2026: Ghostty, just, flash.nvim, and more

I checked out some hot new tools and here’s what I’m using:

Ghostty

A “new” terminal emulator. It’s supposed to be very fast and lightweight.

Why I’m using it:

  • Being able to store my terminal config in a single file. iTerm2, which I was using before, has very complex GUI menus which I never fully understood.
  • It seems fast, but iTerm2 also seemed fast enough.

  • iTerm2 features that Ghostty supports
    • Global hotkey for visibility
    • Loading color themes (Dracula)
    • Copy on select
  • iTerm2 features that Ghostty doesn’t support
    • Ultra-thin tabs (Compact mode)

My config:

theme = Dracula
font-family = Menlo
font-size = 14
font-thicken = true
keybind = global:alt+backquote=toggle_visibility
copy-on-select = true
macos-titlebar-style = tabs # No iterm2 compact mode equivalent

Dracula

It’s a dark terminal color scheme. I like it.

just

If you ever wrote a Makefile just to conveniently run some commands, just is that but designed explicitly for this use case.

Benefits:

  • Full support for targets and dependencies
  • No need for .PHONY targets.
  • Can list out all targets with a command line
  • Can use a shell interpreter and write just scripts (this is awesome)
  • targets can take arguments, allows for reusing targets within the justfile
  • Can you custom script interprets in the body of targets

Downside: You can’t explicitly control parallelism with -j. You can only use a [parallel] annotation in the justfile.

flash.nvim

A better version of EasyMotion, vim-sneak, hop, leap etc. Jump to any character on screen immediately. Also has LSP support.

There is an unofficial VSCode extension too.

zoxide

Easily jump around directories.

lazygit

Been using this for a while, but an extremely powerful git client. Ideal tool for rebasing and cleaning up branch history.

Old stuff

Not-new parts of my setup I continue to use:

  • VSCode
    • C-mantic, clangd, search-in-current-file, fuzzy-search, All Autocomplete
  • fish shell
  • nnn

How to ask for feedback at work

Here’s how I successfully asked for feedback from a colleague at work recently.

  • I did some personal reflection and wrote a self-evaluation. I reflected on the main areas where I observed problems, friction, or opportunities to improve as a coworker.
  • I emailed my colleague saying: It’s been a while since I asked for feedback from the team, I’m always trying to improve, and would appreciate any thoughts you have in this area for me. I attached my self-evaluation at the bottom. I asked if they would be open to a 25-minute meeting to chat about this. They could either prepare thoughts beforehand, or we could just chat about the self-evaluation and explore in real time.
  • They agreed, and we did the call. I shared my screen with a copy of the self-evaluation, so we had something to look at, and so I could annotate with notes in realtime.

In the past, I sent such an email without the self-evaluation attached, or worse, with a long list of specific feedback questions I wanted answered.

The self-evaluation + call strategy works well because it reduces the amount of creative energy the feedback giver needs to spend.

Rather than reflecting from scratch on your performance (which they may not even have close to mind), they have a set of initial prompts which might spur ideas.

Doing your own self-evaluation also shows that you’re self-aware of your own weaknesses.

Making some “critical” comments about yourself can make it easier for a colleague to give feedback that they might be shy about. They might not want to sound negative, and might be reluctant to bring something up, but if you were able to anticipate it and “pre-critique” yourself, that makes it easier for them to agree and possibly elaborate on the topic.

What to know about GPLv2 vs GPLv3

An important thing to note about the GPLv3 is that it is not just an incremental improvement or modernization of the GPLv2, contrary to its name.

It’s effectively a different license that’s even one level stricter than the GPLv2 in a substantial way.

In addition to the base requirements of the GPLv2 for releasing source code for distributed binaries, it goes one step further and requires that modified binaries can be installed onto the hardware that distributed the original binaries.

Unlike simple release of source code, this has engineering implications for hardware manufacturers. It prevents “locked down” devices and forces devices to be open and reprogrammable. “Tivo-ization” is a term referring to the practice of “locking down” a device, which is often used in discussions around GPLv3.

This is why Linus Torvalds refused to adopt GPLv3 for Linux, because in his view, this was going too far.

So if you’re in the market for a copyleft OSS license, keep in mind that GPLv3 is not automatically the best fit, and should not necessarily be automatically used over GPLv2 just because it’s the newest version in the “GPL series”.

It represents an additional step of strictness on the restrictiveness scale. If you’d like distributors to release source code, but don’t necessarily need them to make their devices openly programmable, GPLv2 is still the license to use.

Resources:

How to be a more effective professional engineer

These are tips I’ve been applying in my professional life as an individual contributor on a software development team.

Better awareness of time

This is a foundational practice which concretely helps me with better standup reports, team retros, and stress management (see below).

I have two time tracking systems, coarse and granular.

The coarse system is designed to help me see at a high level what I’ve been up to over the last days/week/months.

The granular system is designed to provide insights about how much time I’m spending on specific types of work. It also gives me more mindfulness about how much time I actually have to do work.

Concretely, the coarse system is a spreadsheet. Every row is a week. Every workday gets three columns: Morning, Early Afternoon, Later Afternoon. These correspond to natural chunks of time for me, and may differ for you. I fill in roughly what I did during each of these 2-3 hour buckets. The massive benefit of a spreadsheet is how information-dense it is β€” you can easily view months at a time like this.

Concretely, the granular system is Toggl Track. I don’t use the automatic app-based tracking, and manually track the time. Although this is the “granular” system, it’s still somewhat coarse grained to make the tracking overhead manageable. For me, the main categories are:

  • Main Dev Work (i.e. The primary work I do as part of my dev team)
  • Pair Programming
  • Code Review
  • Meetings
  • Personal Dev Maintenance (i.e. Maintenance of my dev environment)
  • Meta/Reflection (i.e. Time for weekly reviews, GTD, etc)
  • Admin
  • Misc

Better standup reports

I used to give unfocused and rambly stand-up reports. To improve this, I started taking 1-2 minutes before standup to prepare my report.

I use a standard framework for structuring my report.

  • Did: What I did since yesterday’s report
  • Doing: What I’m doing today
  • Blocked: What I’m blocked on, waiting for, or struggling with (that I could use help from colleagues with)

To help remember what I did (even if it was just yesterday), I rely on my coarse time tracking.

Better team retros

To remember what happend in the last sprint (two weeks), I use my coarse time tracking system. I also keep a virtual notebook with retro thoughts as they come up throughout the sprint.

Better capacity planning

I fill in vacation, holidays, conferences, and other absences in my coarse time tracking system. Since the coarse system is so zoomed-out, it’s very easy to anticipate absences coming up and give my team warning about them. This is especially helpful when the team is doing planning work, so we can adjust work expectations based on capacity.

Better use of small blocks of time

Sometimes I finish a major effort, and have only 20 minutes either before a meeting, lunch, or the end of the day. I used to just start on whatever was top of mind for me, which is often large Main Dev Work β€” features, stories, or bugs that require longer periods of focus time.

Choosing this type of work for a short time block isn’t always a good choice, since there’s not enough time to properly get into the topic.

To help this, I

  1. Stay grounded in my calendar through the day, and keep an awareness of upcoming meetings, end of the day, etc
  2. Maintain lists of things I could do, so I have awareness beyond what happens to be most top of mind

There are certainly smaller tasks of various types that I could do in 20 minutes (admin, dev env maintenance). Much of better time management is choosing tasks that are appropriate for the given time available.

Better focused work

Again, this is time related. I noticed that if I didn’t get a solid focus session in the morning, the next earliest time to start one might be as late as 4/4:30p due to meetings. But by that point, I’m kind of tired and have less time to ask for help or pair if necessary since colleagues start to sign off.

I started really prioritizing my morning flow, and trying as hard as possible to ensure that I can have at least 2.5-3 hours of solid work time in the morning when I’m more fresh.

Better resuming of work

I used to leave my digital workspace a mess when I signed off, with browser tabs, terminal tabs, and IDE windows everywhere. This could help preserve some context, but often just created a mess to start my day. I started doing a daily sign off ritual where I clean up all these tabs, and create a clean workspace for the next day, ideally even with the right tabs and IDE windows open for my next morning flow.

Better ending of work

I used to often overwork, especially when working from home. Now, I explicitly plant an event in my calendar for the last 15 minutes of the work day to wrap up and do my sign off rituals. I also adopted a mindset of being extra aware of time passing throughout the day, and having my calendar simply open on a side monitor.

This mindfulness helps me anticipate the fast-approaching end of the day and helps me not blow past it and overwork.

Better expectations around work

After I finished one task, I used to simply start on whatever was next, regardless of how much time I had left in a day, or how large the task was. (I already mentioned this above). The implicit work model is that as long as I’m at work, I simply grind through the work. This isn’t necessarily the healthiest mindset because you’re never really “done”. The day simply ends, often in the middle of a task.

I adjusted my expectations to be more realistic about energy management. I now focus on making one impactful piece of progress per day, ideally during my morning flow session, ideally on a high impact/importance/leverage task. If I’ve done that by the end of the day, I can take pride in a solid day’s work and sign off guilt-free.